Use TypeSafe Jev for the simple, repeated decisions inside an AI workflow, like routing a lead, scoring how urgent a request is, or answering a yes-or-no question. Jev picks its answer from options you define, runs up to 200 times faster than frontier models, and costs about four pennies per million input tokens. At TJ Digital, we use AI in every workflow to deliver about four times the work at the same rates, and picking the right model for each step is part of how we do it.
Jev is a narrow tool built for one job. It’s fast and cheap enough to use on every small decision in a process, and a lot of the decisions we hand to AI are small ones. That’s why I think Jev might change how we build our workflows.
Table of Contents
ToggleWhat Is TypeSafe Jev?
TypeSafe Jev is the first public model from TypeSafe AI, a San Francisco lab that released it on September 15, 2026. TypeSafe calls it a System One model, a reference to Daniel Kahneman’s split between fast, intuitive thinking (System 1) and slow, deliberate reasoning (System 2). You feed it natural language, just like you would with a generative large language model.
Jev doesn’t generate any text, so it works like a classifier. According to TypeSafe’s launch post, Jev’s end-to-end latency is 70 to 500 milliseconds, while frontier models take anywhere from 3 to 329 seconds.
Jev’s pricing is just as lopsided. Jev charges $0.042 per million input tokens, and output is free. Large language models charge $0.20 to $10 per million input tokens, and their output tokens usually cost about five times more.
In TypeSafe’s workflow tests, Jev made comparable decisions for less than 1% of what frontier LLMs cost.
@tjrobertson52 When to use Jev instead of a full LLM: it can’t hallucinate, runs 200x faster, and costs 4 cents per million tokens #AI #AITools #Automation
♬ original sound – TJ Robertson – TJ Robertson
How Does Jev Respond Without Writing Text?
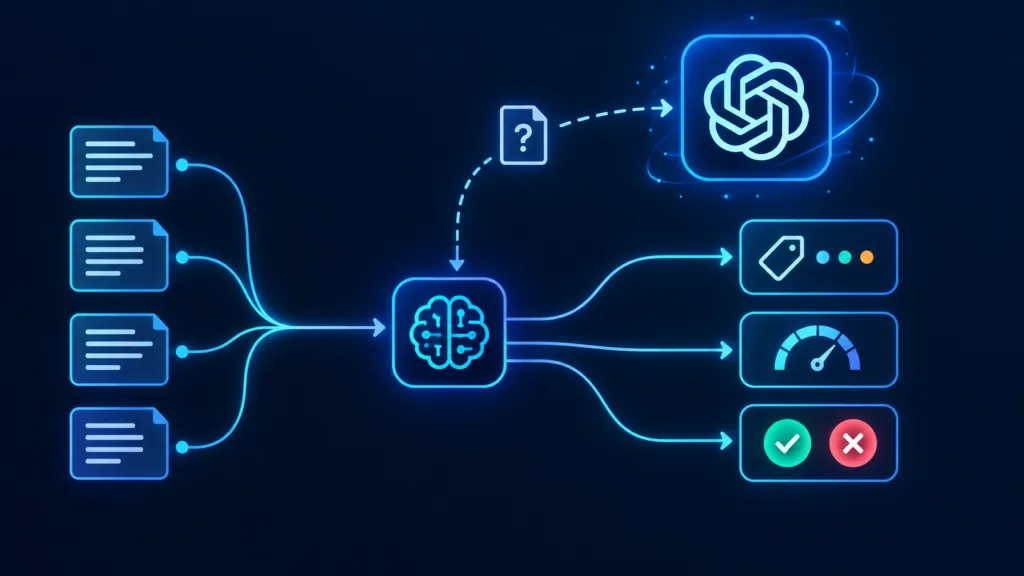
Jev can respond in three ways:
- Pick from a list. You give it a set of options, and it chooses one. It’s a good fit for categorizing or routing, like sorting an email into sales, support, or spam.
- Grade on a scale. It scores something on a scale you define, like rating a support ticket’s urgency from 0 to 100.
- Answer true or false. It returns a yes-or-no answer with a probability that shows how confident it is in that answer.
TypeSafe calls these Choice, Score, and Noul questions. Every answer includes a confidence score, and TypeSafe trained Jev so higher confidence lines up with higher accuracy. The confidence score lets your system act automatically when Jev is confident and send the unclear cases to a person.
Now, yes, only answering in these three formats is a major limitation, and Jev won’t replace large language models. Still, the more you think about it, the more useful you realize it could be. Its biggest limitation is actually a strength in the areas where it’s best used.
Can Jev Hallucinate?
No. As TypeSafe puts it, Jev can’t hallucinate. Every answer it gives has to be one of the options you defined, so it can’t invent a category, break your format, or wander off into a paragraph.
Format errors matter once AI runs inside an automated process, because one bad output can break every step after it. On TypeSafe’s own structured output test, GPT-5.6 Terra returned invalid structured output 0.58% of the time and Claude Opus 5 did it 5.73% of the time. Jev’s error rate is zero by design, since it can’t produce anything outside the answers you set up.
Jev can still be wrong. It can pick the wrong option from your list, sometimes with high confidence.
How Accurate Is Jev Compared to Claude and GPT?
Jev’s accuracy is slightly below the top models, like Claude Opus 5 and GPT-5.6 Sol. What you get in return is speed and price. TypeSafe tested Jev on four business workflows, covering security incident response, AI agent monitoring, invoice processing, and customer service.
DataCamp’s breakdown of those tests lays out the results:
| Model | Accuracy | Cost per case | Time per case |
| TypeSafe Jev | 67.8% | $0.0004 | 0.4 seconds |
| GPT-5.6 Terra | 67.9% | $0.0304 | 10.1 seconds |
| Claude Opus 5 | 73.1% | $0.1761 | 37.8 seconds |
| GPT-5.6 Sol | 74.1% | $0.0836 | 23.3 seconds |
Jev matches GPT-5.6 Terra’s accuracy within a tenth of a point at about 1/76th of the cost and 25 times the speed. Opus 5 and Sol keep a 5 to 6 point edge, which matters most when you’re making a small number of high-stakes calls. These are TypeSafe’s own numbers, scored against the average answers of OpenAI’s GPT-6 Astra and Anthropic’s Fable 5.1, and nobody has reproduced them independently yet.
How Is Jev Different From a Traditional AI Classifier?
Jev can classify any text you give it without being trained for the task first. In machine learning terms, that makes it a zero-shot classifier.
A lot of people will point out, “TJ, we’ve had classifiers forever, and they’re even faster and cheaper sometimes.” They’re right about that. But as far as I’m aware, all the classifiers currently in production are trained for a specific purpose.
A traditional classifier needs labeled examples and a training run before it can sort anything, and it only handles the one task it learned. With Jev, you just give it the input and the possible responses, and it does the job.
Here’s how the three options compare:
| Feature | Traditional classifier | TypeSafe Jev | Frontier LLM |
| Setup | Train on labeled examples for each task | Define the question and answers in each request | Write a prompt |
| Output | Labels from one fixed set | Your options plus a confidence score | Free-form text |
| Speed | Often faster than Jev | 70 to 500 milliseconds | Seconds to minutes |
| Writes text | No | No | Yes |
| Best for | One narrow task at huge volume | Lots of different simple decisions | Writing, reasoning, and code |
When Does Jev Make More Sense Than an LLM?
Jev makes more sense than an LLM for decisions you make often, where you already know every possible answer. When I first heard Jev only responds with predefined answers, I wondered how useful it could be.
Think through your own processes, or the ones you’re handing off to Fable 5.1 or GPT-6 Astra. There might be 100 decisions in that process, and 95 of them might be simple classification, the exact kind of problem Jev handles well. Using Fable or Astra for those decisions is like using a nuclear bomb to remove a weed from your yard.
Here are some everyday business decisions that fit Jev:
- Routing leads. Which service is this contact form submission asking about, and who on your team should get it?
- Filtering spam. Is this form submission a real inquiry or junk?
- Scoring urgency. How urgent is this support request on a scale from 1 to 10?
- Triaging reviews. Is this review positive, negative, or mixed, and does it need a reply today?
- Checking content. Does this draft mention a competitor, and does this claim need a source?
- Checking other AI. Did an AI agent’s output follow the rules you gave it? TypeSafe pitches this kind of guardrail as one of Jev’s main jobs.
Large language models still own anything that needs words. Jev can’t write an email, summarize a call, generate code, or explain why it chose an answer. The missing explanation matters for any decision you might need to audit later.
The setup I expect to see most is the two working together. Jev makes the fast decisions, and an LLM does the writing when writing is needed. When Jev’s confidence is low, the case moves up to a smarter model or a person.
At TJ Digital, we already route tasks to different models based on what each model does best. Until Jev is widely available, a faster, cheaper model like Claude Sonnet 5 is still a solid pick for classification work.
Will System One Models Change How We Use AI?
Probably. I don’t know if it’s Jev specifically that’s going to change how we use AI, but I think TypeSafe has demonstrated that there’s a better way to handle these kinds of classifications. Maybe Anthropic and OpenAI were already doing this internally, but this is the first real demonstration we’ve seen.
OpenAI and Anthropic already use classifiers to route requests to more efficient models. As far as we know, though, those classifiers are trained on that one specific task. The approach we’re seeing from Jev could open up a whole new category of efficiency.
In the short term, I think there are going to be a lot of uses for this kind of technology in our normal workflows. Long term, I assume it will just be baked into the major models.
TypeSafe named Jev after economist William Stanley Jevons, who noticed that more efficient steam engines led to more coal use. The company expects cheaper AI to drive more demand the same way.
Jev admittedly isn’t as smart as the frontier models. This is TypeSafe’s first public model, though. If the technology proves useful, I imagine we’re going to see much more capable versions soon.
How Do You Get Access to the Jev API?
Jev is in early access, and TypeSafe says it’s bringing developers off the waitlist as quickly as it can. The API comes with Python and JavaScript SDKs. Developers who don’t want to wait can already call Jev through Vercel’s AI Gateway and Cloudflare.
For most business owners, Jev will show up inside automations a developer or agency builds for you. The useful step today is to list the processes you’ve handed to AI and mark the steps that are simple decisions with known answers. Those steps are where the time and cost savings are.
What Are Common Questions About TypeSafe Jev?
How much does Jev cost per million tokens?
Jev costs $0.042 per million input tokens, or about $42 per billion. Output tokens are free.
Can Jev write text or explain its answers?
Jev can’t write text or explain its answers. It only returns the choices, scores, and yes-or-no probabilities you define, so anything written still needs a large language model.
Who built Jev?
Jev comes from TypeSafe AI, founded by Diogo Almeida. Before TypeSafe, Almeida worked at OpenAI on the research behind ChatGPT.
How fast is Jev?
TypeSafe reports response times of 70 to 500 milliseconds per call. On its workflow tests, Jev ran up to 193.6 times faster than comparable large language models.
Does Jev replace ChatGPT or Claude?
Jev is built to work alongside ChatGPT and Claude. It handles fast, structured decisions, and a large language model handles writing, reasoning, and open-ended work.
How Do You Pick the Right AI Model for Each Task?
Start with the cheapest model that handles each step reliably, and only move up to a frontier model when the step needs reasoning or writing. At TJ Digital, that’s the approach we take with our own workflows, and we pass those savings on to our clients.
Send me your questions about AI workflows through our contact page. Every message comes straight to me.